
by SQLStack
Load data into your warehouse. Fast.
See the plan before any data moves.
Website · Docs · Quickstart · Benchmarks
SQLLoad loads Postgres tables, files and Python sources into Snowflake, Databricks, DuckDB or
Parquet files. sqlload plan shows every table, column type, write strategy and route before
anything is created or loaded. Where Snowflake or DuckDB can load your files exactly by itself,
the files never pass through SQLLoad. It is written in Rust and is open source under Apache-2.0;
Python is needed only for Python sources.
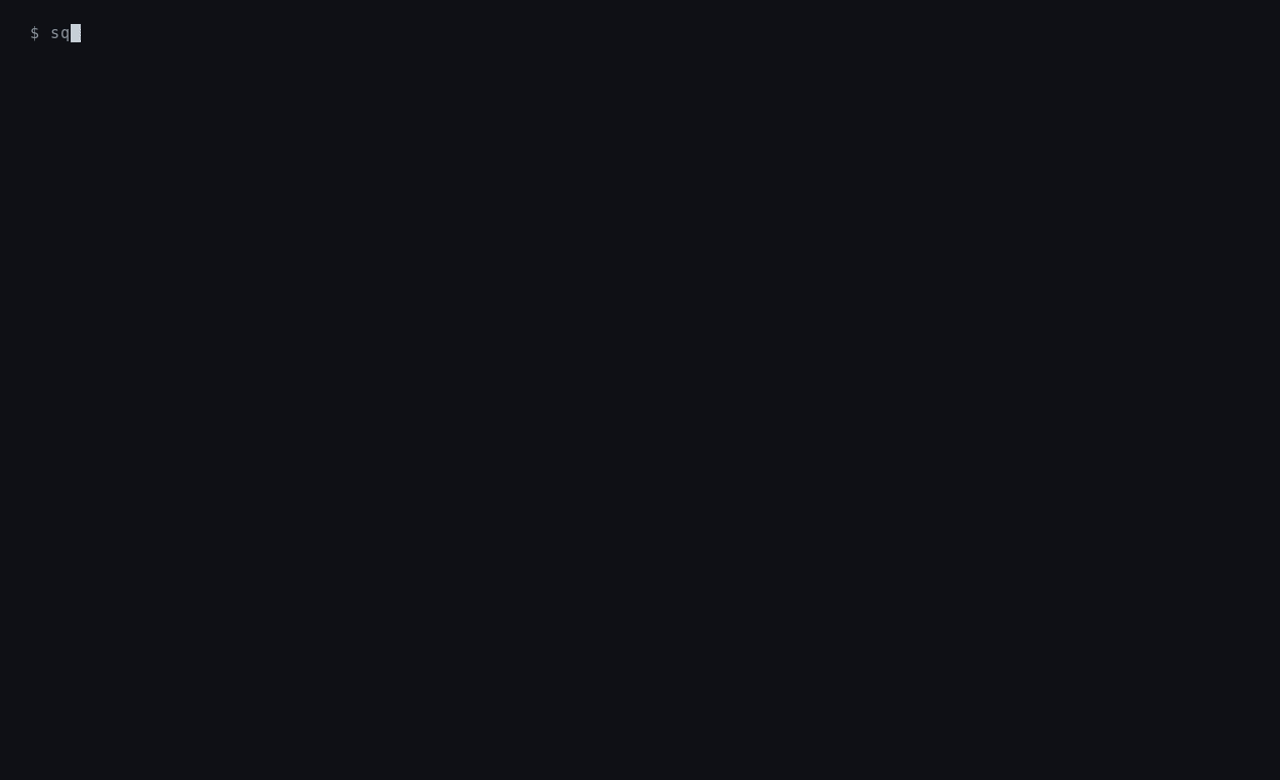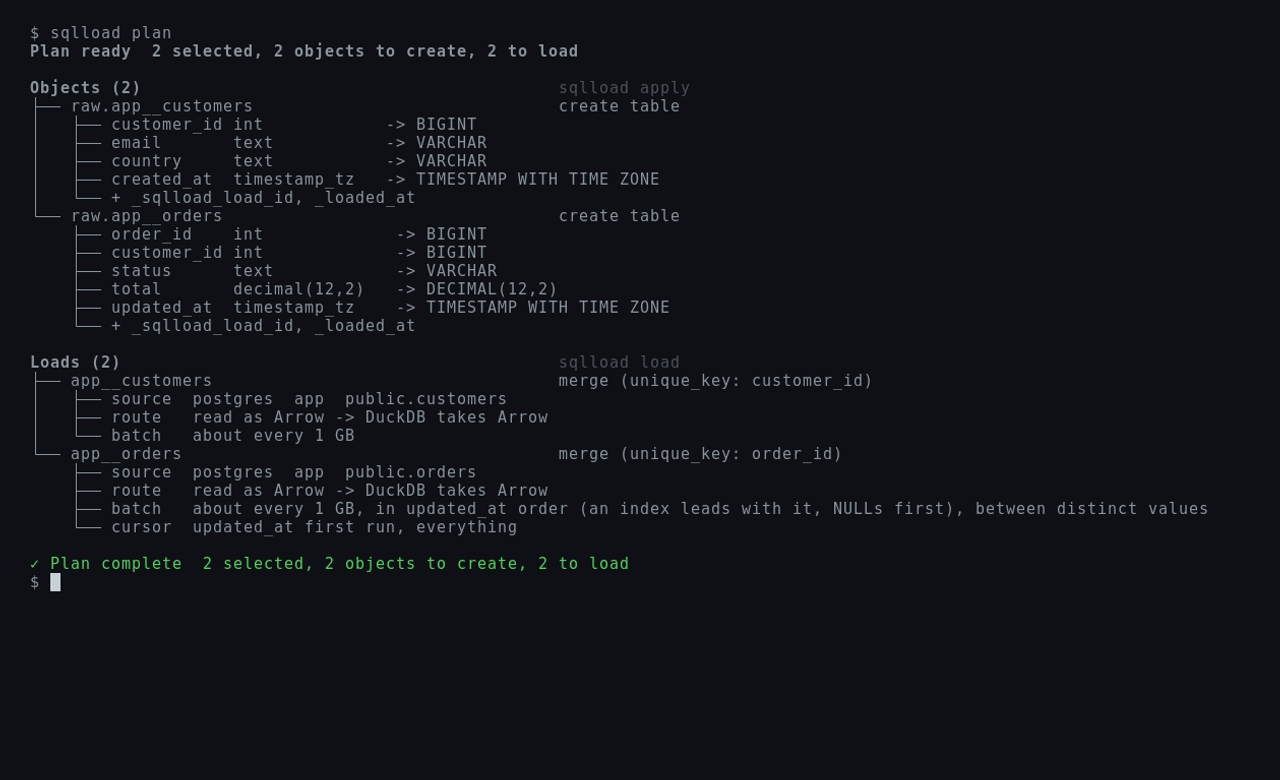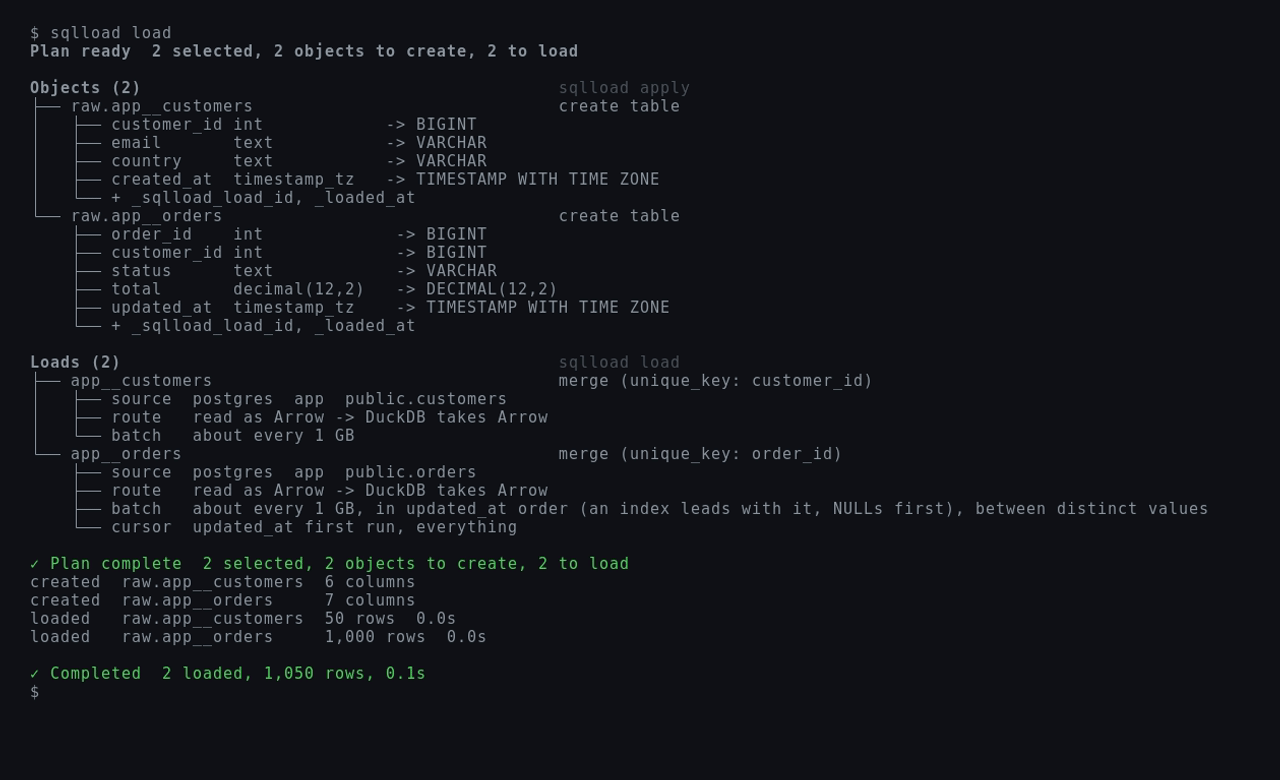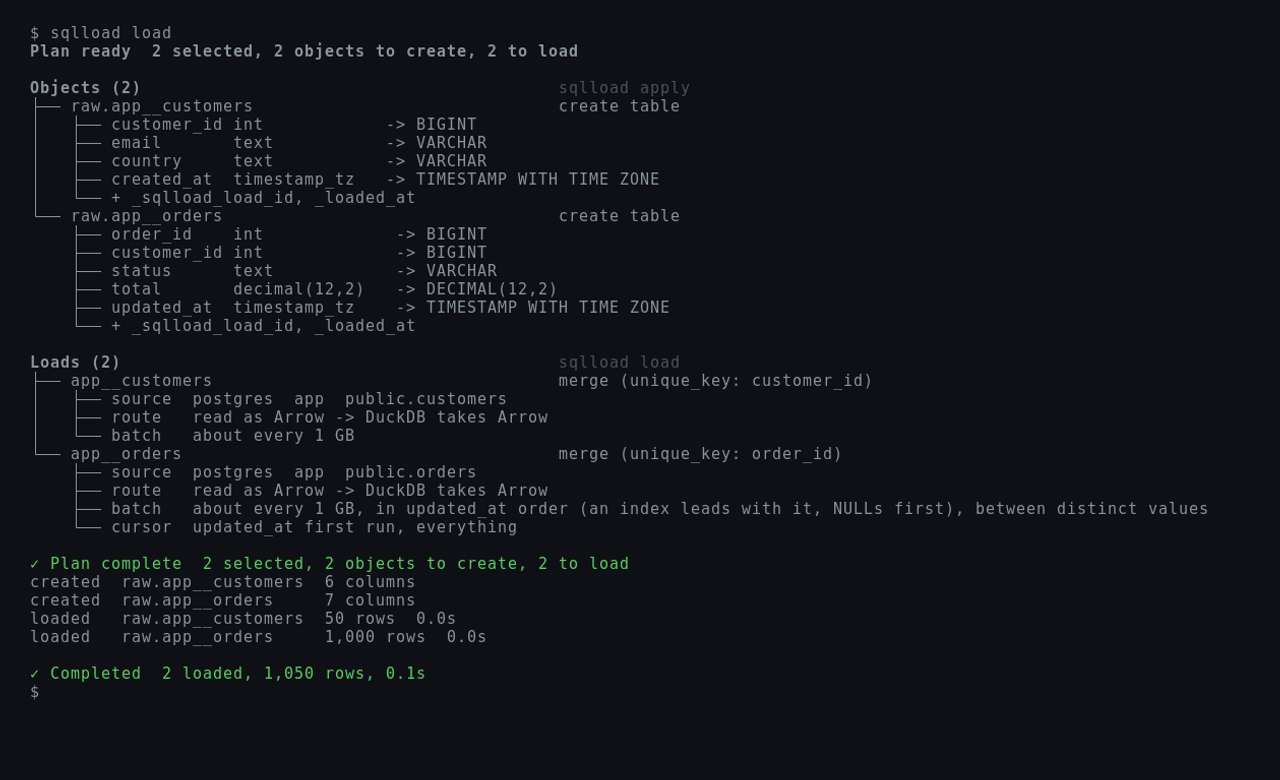
sqlload plan on the quickstart project shows the tables it
would create from Postgres, each column's DuckDB type and how each table loads. sqlload load
then creates and fills them.
uv tool install sqlload
sqlload copy orders/ duckdb://shop.duckdb#raw.orders
sqlload copy loads one table once and needs no configuration file. Here a folder of Parquet
files becomes a DuckDB table; the plan prints first:
$ sqlload copy orders/ duckdb://shop.duckdb#raw.orders
Plan ready  1 selected, 1 object to create, 1 to load

Objects (1)                                         sqlload apply
└── raw.orders                                      create table
    ├── order_id   int            -> BIGINT
    ├── customer   text           -> VARCHAR
    ├── total      float          -> DOUBLE
    ├── ordered_at timestamp_tz   -> TIMESTAMP WITH TIME ZONE
    └── + _sqlload_source_file, _source_version, _source_row, _load_id, _loaded_at

Loads (1)                                           sqlload load
└── orders                                          replace
    ├── source  files  orders/  parquet
    ├── files   1 to read of 1 listed
    ├── route   DuckDB reads directly from orders/ (nothing through the loader)
    └── batch   1 batch of whole partitions, up to 1,000 files or about 1 GB per commit; each batch's footers are combined, so later batches may add columns

✓ Plan complete  1 selected, 1 object to create, 1 to load
created  raw.orders  9 columns
loaded   raw.orders  3 rows  0.0s

✓ Completed  1 loaded, 3 rows, 0.1s
Add --print-toml to print the same copy as a sqlload.toml project, which loads its tables with
sqlload plan, sqlload apply and sqlload load. The
quickstart walks through one.
| Sources | Targets |
|---|---|
| Postgres tables, and Postgres changes from a logical replication slot | Snowflake |
| Parquet, CSV, JSON and NDJSON files in S3 or a local folder | Databricks |
| Python sources, including HTTP APIs | DuckDB |
| Parquet files in S3 or a local folder |
See Supported systems for which combinations and write strategies each supports.
Postgres change data capture. A postgres_cdc source copies every table under a snapshot on
the first sqlload load. Each later load applies the inserts, updates and deletes committed since
the last one, from a logical replication slot, as merge or changelog into DuckDB, Snowflake or
Databricks, or as a changelog into Parquet files.
From 0.18.0, columns added, dropped or widened while streaming carry through. From 0.20.0,
sqlload load app --follow keeps streaming, writing a batch every 10 seconds by default.
See Postgres CDC.
Kafka exporter. A separate mode, sqlload run, streams Kafka topics into Snowflake. Its
configuration is in sqlload.example.toml; see the
Kafka exporter docs.
The sqlload package is a native Python extension for CPython 3.10 or newer, and runs Python
sources in the same process as the loader. sqlload-cli is the same command as a standalone
executable, without Python and without Python sources. Install only one of them, because both
provide a sqlload command (uv tool install sqlload-cli for the executable). Both are released
for Linux (x86_64 and aarch64, glibc 2.28 or newer) and macOS 11 or newer (arm64). See
Install.
- Documentation: install, quickstart, concepts, the CLI and Python references, configuration and supported systems.
- The
sqlloadpackage README: Python and HTTP sources, batches, logged state, change data capture, and how rows reach Snowflake, Databricks and DuckDB. - Benchmarks: SQLLoad, dlt and ingestr loading the same data into DuckDB and Snowflake, with the method, versions and figures.
- Changelog.
make check            # fmt, clippy, fensu
make test-unit
See CONTRIBUTING.md for the container and Python tests and the rules the checks enforce.
Apache-2.0.