
Multilingual, non-autoregressive System 1 decision engine. Typed decisions over 100+ languages in a single forward pass — 33 ms — trained with reinforcement learning against strictly proper scoring rules (RLCD), with a router that picks the right checkpoint per request.




python -m pip install layaPython 3.10 or newer. Optional extras: laya[serve] (HTTP server), laya[mcp] (MCP server), laya[langchain] (LangChain and LangGraph), laya[onnx] (ONNX Runtime), laya[fast] (TileLang GPU fast path). Step-by-step setup for each platform, CPU-only or GPU PyTorch builds, and troubleshooting are in Installation details.
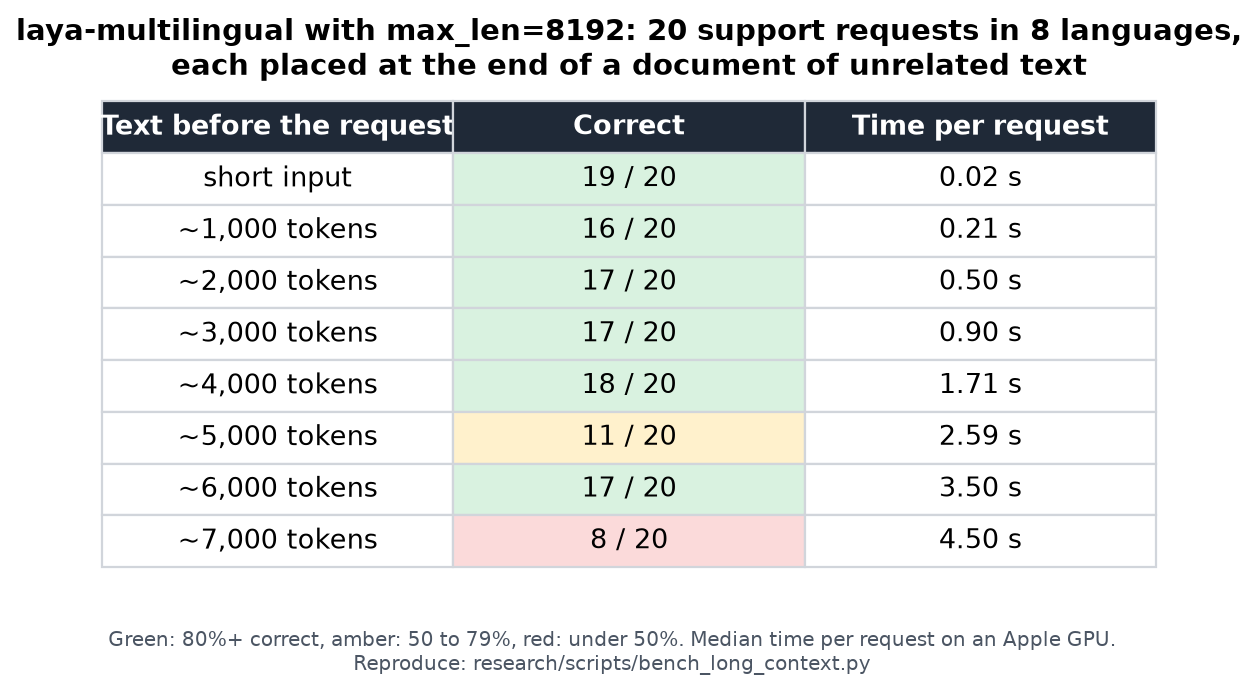
Long documents. laya-multilingual reads up to 8,192 tokens with max_len=8192. Measured accuracy and time by document length, reproducible with research/scripts/bench_long_context.py:
Long documents:
laya-multilingualreads up to 8,192 tokens. It ships with a 1,024-token limit that cuts long documents off, so passmax_len=8192for them:result = router.predict(long_document, questions, model="multilingual", max_len=8192)In the table above, 16 to 18 of 20 requests were answered correctly with up to about 4,000 tokens of text before them; beyond that results vary (8 to 17 of 20), so check long-document accuracy on your own data. Short inputs give identical answers with
max_len=8192, and speed follows the input's real length, not the limit: short inputs are unchanged, and a 4,000-token input takes about 1.7 s on an Apple GPU. Name the checkpoint withmodel="multilingual", since long mostly-English text would otherwise route to the English checkpoint.
from laya import Router

router = Router()  # downloads a checkpoint on first use; Router(preload=True) loads all three up front

state = "Hi, we were billed twice for March. Please refund the duplicate today or we will cancel our plan."
questions = {
    "department": {"type": "choice", "instructions": "Which department should handle this?",
                   "criteria": {"billing": "invoices, payments, refunds",
                                "technical": "bugs, outages, system errors",
                                "other": "everything else"}},
    "urgency": {"type": "score", "instructions": "How urgent is this?",
                "criteria": ["not urgent", "soon", "blocking"]},
    "churn_risk": {"type": "noul", "instructions": "Does the user threaten to cancel or leave?"},
}

result = router.predict(state, questions)
print(result["answers"]["department"]["choice"])  # billing
print(result["answers"]["churn_risk"]["noul"])    # probability the answer is yes
print(result["routing"]["model"])                 # english
The same call works in any of 100+ languages. The Router detects the script and language and sends non-English text to laya-multilingual:
for text in ["मुझसे मार्च में दो बार शुल्क लिया गया, कृपया डुप्लिकेट राशि वापस करें।",
             "La aplicación se cierra cada vez que abro la configuración."]:
    r = router.predict(text, {"department": questions["department"]})
    print(r["routing"]["model"], r["answers"]["department"]["choice"])
# multilingual billing
# multilingual technical
From the command line, laya "My payment failed twice" --preset triage answers a ready-made question set. More in the full quickstart and the docs.
The shipped checkpoints work zero-shot, but fine-tuning on decisions from your own domain is where accuracy jumps. On the typed-decisions benchmark (2,000 decisions across four workflows), the fine-tuned laya-typed-decisions checkpoint scores 0.766 accuracy, against 0.362 for the base English checkpoint on the same decisions.
Fine-tuning notebook: runs the whole loop on Kaggle's free 2x T4 GPUs (build the dataset, train, fit calibration temperatures, evaluate, and push the result to the Hub). Details in Fine-Tuning.
nandhakishorm.github.io/laya: guides for prediction hooks, schema-driven decisions, Docker and LangChain and LangGraph, plus a full API reference.
- Long documents with
max_len=8192. A measured table below Installation shows accuracy and time forlaya-multilingualby document length, from a reproducible benchmark: strong up to about 4,000 tokens of text, more variable beyond. - Installation, quickstart and documentation first. This README now opens with how to install Laya, runnable English and multilingual examples, how fine-tuning improves accuracy, and where the docs are.
- Documentation site at nandhakishorm.github.io/laya, with an API reference generated from the docstrings.
The code is unchanged from the last runtime release, whose fixes are:
- Sturdier fast path. After a CUDA out-of-memory error, the fallback to CPU switches the TileLang fast path off first instead of retrying on CUDA. A
choicequestion with a single option no longer crashes it, requests longer than it was built for get a clear error, and concurrent calls can no longer overwrite each other's CUDA-graph buffers. - Server and runtime.
laya-servedrains its inference pool on shutdown and returns 401 for a malformed bearer header, andONNXAgentmatchesAgenton empty question sets and long conversation lists. - Smaller fixes. The
layacommand prints the right probability for a choice, LangChain remote calls refuse cross-origin or HTTPS-downgrade redirects, andAGENTS.mdgives AI coding assistants the contribution rules.
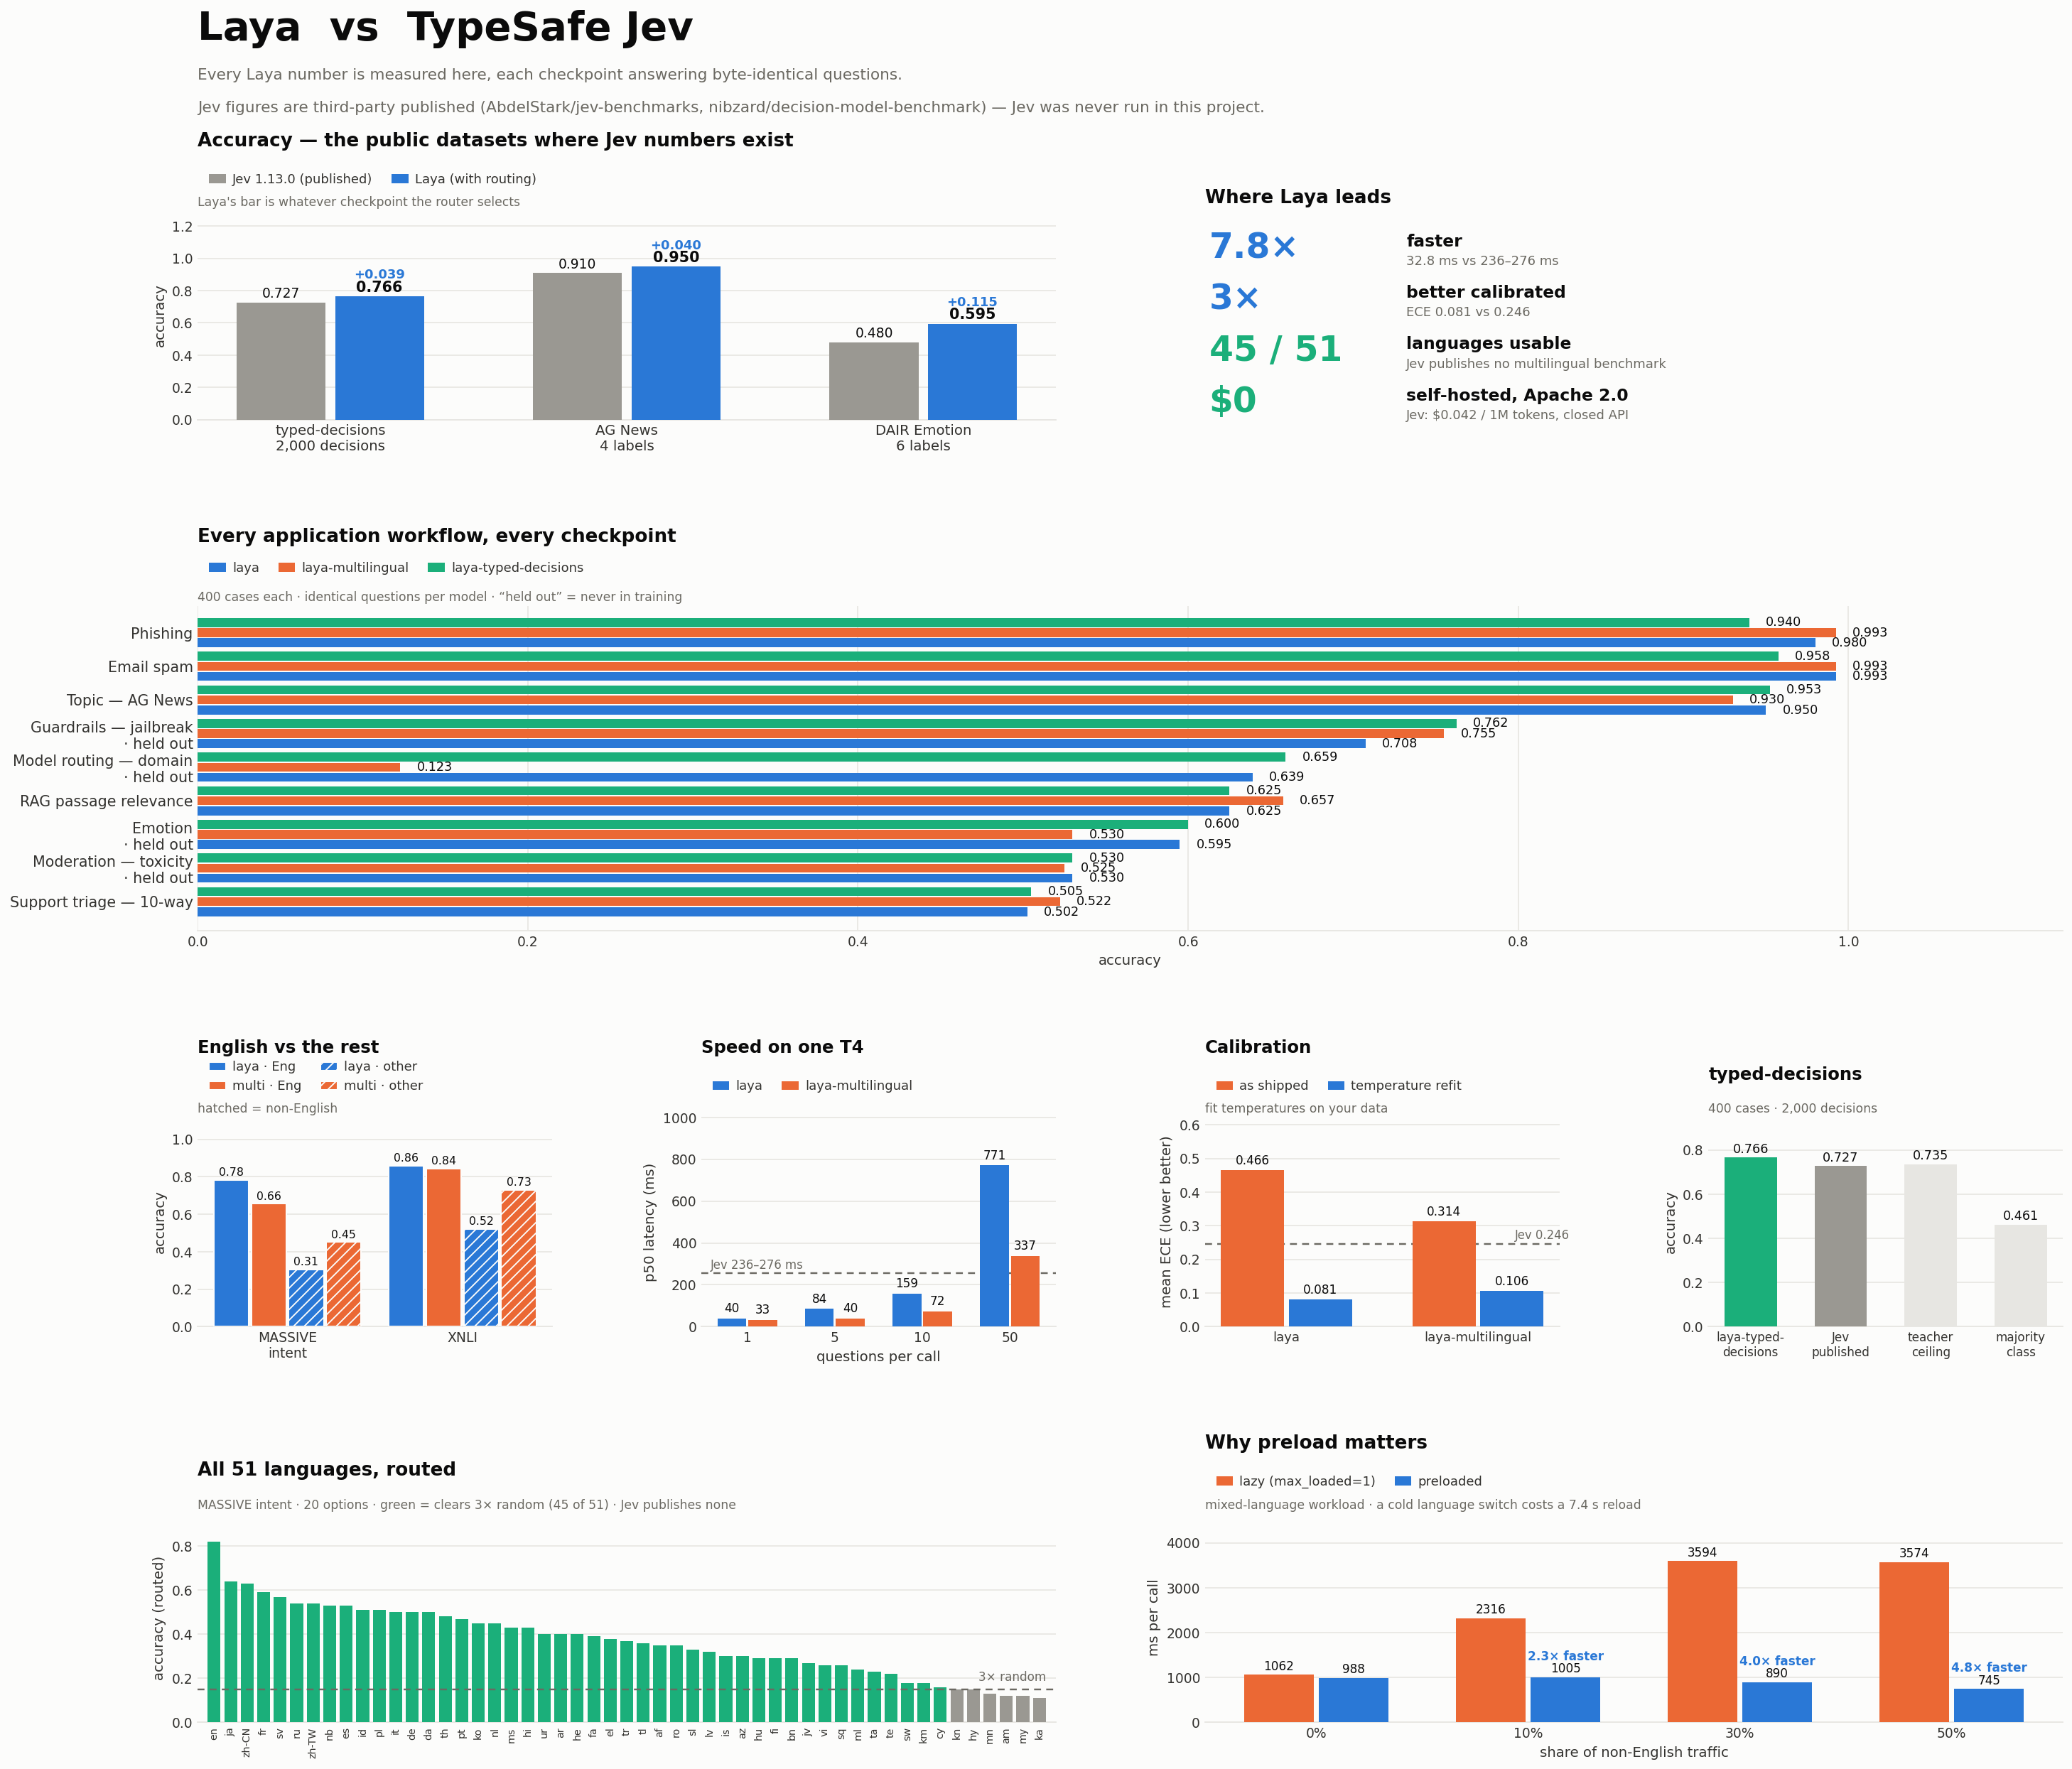
Laya evaluates typed questions (choice, score, noul) over any state (text, email, ticket or JSON document) in a single forward pass — 33 ms for one question, 7.2 ms/question batched, measured on a T4. No text generation, so nothing to parse and nothing to hallucinate.
Three checkpoints, and a Router that picks between them per request:
| encoder | params | context | use it for | |
|---|---|---|---|---|
laya |
ModernBERT-large | 421M | 512 | English |
laya-multilingual |
mmBERT-base | 322M | 1024 (up to 8,192) | 100+ languages, 2x faster |
laya-typed-decisions |
ModernBERT-large | 421M | 1024 | the typed-decisions workflows |
Python 3.10 or newer. The dependencies set that floor: huggingface_hub 1.x, transformers 5.x and torch 2.14 all require 3.10.
Optional PyTorch build selection: If you need a CPU-only or GPU-specific PyTorch build, follow PyTorch's installation guide after creating your virtual environment and before installing Laya. Replace pip or pip3 in the selected command with the environment's Python executable followed by -m pip.
If you already use a virtual environment, install the PyPI release with:
python -m pip install layaFor a new environment, choose the commands for your platform below. Run them from your project directory; the explicit Python paths keep installation and verification in the same environment.
macOS / Linux (with Python 3.10 or newer):
On Debian/Ubuntu, the system Python may require sudo apt install python3-venv before creating a virtual environment. If venv reports that ensurepip is unavailable, install that package and retry.
python3 -m venv .venv
.venv/bin/python -m pip install laya
.venv/bin/python -I -c "import laya; print(laya.__version__)"
Windows PowerShell (this example uses an installed Python 3.11):
py -3.11 -m venv .venv
.\.venv\Scripts\python.exe -m pip install laya
.\.venv\Scripts\python.exe -I -c "import laya; print(laya.__version__)"
Both checks print the installed Laya version without loading a checkpoint. -I excludes the current directory from the import search path, so a local source copy cannot mask a missing installation. Keep using the same virtual environment's Python when running your application.
Intel GPU (XPU)
Install a supported Intel GPU driver first. For an XPU-enabled PyTorch build, install its wheel before Laya; the default PyPI wheel may be CPU-only. PyTorch's validated hardware and OS list is in the Intel GPU guide.
.\.venv\Scripts\python.exe -m pip install torch --index-url https://download.pytorch.org/whl/xpu
.\.venv\Scripts\python.exe -m pip install laya
.\.venv\Scripts\python.exe -c "import torch; print(torch.xpu.is_available())"
For a source checkout, replace pip install laya with pip install -e .. Laya automatically selects an available XPU when no device is specified; you can also request one explicitly with device="xpu" in laya.load() or Router(device="xpu").
Install from GitHub
To use the development version instead of the PyPI release, create the virtual environment above and replace its installation command with the appropriate command below. Git must be installed.
# macOS / Linux
.venv/bin/python -m pip install "git+https://github.com/NandhaKishorM/laya.git"
# Windows PowerShell
.\.venv\Scripts\python.exe -m pip install "git+https://github.com/NandhaKishorM/laya.git"Run the same version check afterward. The GitHub version follows the repository's default branch and may differ from the published release.
Model setup and troubleshooting
Continue with the Router quickstart to run inference. Loading a Hub checkpoint requires access to Hugging Face on its first download; the quickstart's Router(preload=True) loads all three configured checkpoints at construction.
ModuleNotFoundError: No module named 'laya': run both installation and your script with the same virtual environment's Python executable shown above. In an editor, select that interpreter as well.- Missing
rl_agent_config.json: this file ships with a Laya checkpoint alongsidemodel.safetensors; it is not a configuration file you need to create in the source repository. For a local model, pass the directory containing those checkpoint files.
Installing the package also installs a laya command for quick local testing, no script needed:
laya "I was charged twice, please refund"            # routing decision only; works offline, no download
laya "Refactor this service" --predict               # full answers (downloads the checkpoint on first use)
laya "Mein Konto wurde zweimal belastet" --lang de   # force a language instead of detecting it
laya "My payment failed twice" --preset triage       # answer a ready-made preset (triage, email, guard, moderation, router)
laya                                                 # interactive mode
Routing alone never downloads a checkpoint, so it returns in milliseconds. --predict loads the routed checkpoint, which needs network access to the Hugging Face hub the first time; if a checkpoint cannot be downloaded, the CLI says so instead of crashing.
examples/server.py is a self-contained FastAPI app for testing Laya without writing any code:
a two-pane playground (edit the request as a form or as JSON, run it with Ctrl+Enter, read each
answer's full distribution and calibrated confidence, copy it as curl or Python), plus a plain
JSON API (/predict, /predict/batch) for scripting against.
pip install "laya[serve]"
python examples/server.py               # http://127.0.0.1:8000
Open http://127.0.0.1:8000 in a browser for the playground, or hit it directly:
curl -s localhost:8000/predict -H 'content-type: application/json' -d '{
  "state": {"body": "We were billed twice for March. Please refund it today."},
  "questions": {
    "department": {"type": "choice",
                   "instructions": "Which department should handle this?",
                   "criteria": {"billing": "invoices, payments, refunds", "other": "everything else"}},
    "urgency": {"type": "score",
                "instructions": "How urgent is this?",
                "criteria": ["not urgent", "soon", "critical"]}
  }
}' | python -m json.tool
--no-preload loads checkpoints lazily instead of all three up front; --device cuda|cpu|mps
pins the device. See python examples/server.py --help for the rest.
To try the Python SDK in a CPU container, see the Docker Compose quickstart. It runs a sample request and keeps downloaded models between runs.
Laya ships three checkpoints. The built-in Router is the recommended entry point: it evaluates any state in any language, automatically detects scripts and languages in sub-milliseconds, and dispatches to the optimal checkpoint in a single forward pass.
from laya import Router

# Preload checkpoints into memory for instant sub-35ms routing
router = Router(preload=True)

# 1. State in any language or schema
state = {
    "from": "user@acme.com",
    "subject": "Duplicate charge on invoice #4411",
    "body": "Hi, we were billed twice for March. Please refund the duplicate today or we will cancel our plan."
}

# 2. Define your typed questions
questions = {
    "department": {
        "type": "choice",
        "instructions": "Which department should handle this request?",
        "criteria": {
            "billing": "invoices, payments, refunds",
            "technical": "bugs, outages, system errors",
            "sales": "pricing, new contracts",
            "other": "everything else"
        }
    },
    "urgency": {
        "type": "score",
        "instructions": "How urgent is this request?",
        "criteria": ["not urgent", "soon", "critical deadline or blocking issue"]
    },
    "churn_risk": {
        "type": "noul",
        "instructions": "Does the user threaten to cancel or leave?"
    },
    "refund_requested": {
        "type": "noul",
        "instructions": "Does the user explicitly request a refund?"
    }
}

# 3. English state -> automatically routed to laya (ModernBERT-large, 39.5 ms)
res_en = router.predict(state, questions)
print("Department :", res_en["answers"]["department"]["choice"])  # -> billing (confidence: 0.94)
print("Routing    :", res_en["routing"]["model"])                 # -> english

# 4. Hindi state -> automatically routed to laya-multilingual (mmBERT-base, 32.8 ms)
res_hi = router.predict({"body": "मुझसे दो बार शुल्क लिया गया, कृपया पैसे वापस करें।"}, questions)
print("Department :", res_hi["answers"]["department"]["choice"])  # -> billing (confidence: 0.86)
print("Routing    :", res_hi["routing"]["model"])                 # -> multilingual

# 5. Explicit override when you want a specific checkpoint
res_td = router.predict(state, questions, model="typed-decisions")
Every result carries full routing metadata explaining why the choice was made:
res_hi["routing"]
# {
#   'model': 'multilingual',
#   'repo': 'convaiinnovations/laya/multilingual',
#   'reason': 'non-Latin script (devanagari, 100% of letters); the English checkpoint cannot read it'
# }
Inspect a routing decision without running any forward pass:
router.route({"body": "Der Kunde wurde zweimal belastet"}, questions).reason
# "Latin script but language looks like 'de', not English"
Very short Latin-script text often carries nothing that identifies its language ("Quero cancelar", "Esqueci minha senha"). Such text goes to default, which is "english" unless you change it. If most of your traffic is not English, set:
router = Router(default="multilingual")
router.route({"body": "Esqueci minha senha"}).model                 # -> multilingual
router.route({"body": "Please refund the duplicate charge"}).model # -> englishIf a lazy router receives an interleaved workload whose requests route to different checkpoints, calling predict() in a loop can still cause unnecessary checkpoint churn when the required checkpoints exceed the resident cache, for example with max_loaded=1 or when typed-decisions is also used.
Router.predict_batch() routes the full workload first, groups requests by checkpoint, then groups requests with the same question schema within each checkpoint. Each compatible group is dispatched to Agent.predict_batch() so states can share forward passes, and results are restored to the original request order.
requests = [
    {"state": "Please refund invoice 1", "questions": questions},
    {"state": "تم خصم المبلغ مرتين", "questions": questions},
    {"state": "Please refund invoice 2", "questions": questions},
]

results = Router(max_loaded=1).predict_batch(requests)
# results stay in input order while compatible requests are batched by checkpoint
Each item can independently set model, task, lang, or lang_guess. Use route_batch(requests) when you only want the ordered routing decisions without loading any checkpoint. predict_many is an alias for predict_batch.
Requests are validated before model loading. Different requests may use different question schemas; requests sharing both a checkpoint and question schema are passed together to Agent.predict_batch().
Prediction hooks installed on the Router run once per request, as they do for predict(), so a redaction hook rewrites every state before the model sees it. Requests that share a checkpoint run all their start hooks before their shared forward pass; see docs/hooks/lifecycle.md.
You can also bound the Agent-level forward-pass batch size:
results = router.predict_batch(requests, batch_size=8)On a shared benchmark (17,416 questions, one T4 GPU, identical questions per model):
| Benchmark / Task | English (laya) |
Multilingual (laya-multilingual) |
Router (Routed) |
|---|---|---|---|
| MASSIVE intent, English | 0.783 | 0.657 | 0.783 |
| MASSIVE intent, 13 other languages | 0.306 | 0.451 | 0.451 |
| XNLI, English | 0.860 | 0.843 | 0.860 |
| XNLI, 14 other languages | 0.521 | 0.731 | 0.731 |
| Languages usable (>3x random) | 23 / 51 | 45 / 51 | 45 / 51 |
| Latency, 1 question (T4 GPU) | 39.5 ms | 32.8 ms | 32.8 ms |
| Latency, 10 questions batched | 158.6 ms | 72.3 ms | 72.3 ms |
The English checkpoint collapses on non-Latin scripts (Khmer scores 0.000 accuracy at 0.952 confidence). Because the model stays confident while being wrong, confidence gating cannot save you. Router detects the script in <0.5 ms pure Python before the forward pass.
A cold checkpoint build costs seconds; language detection costs microseconds. The lazy default keeps two checkpoints resident — english and multilingual, the only two automatic routing chooses between — so a language flip costs detection only once each has been built. max_loaded=1 rebuilds the checkpoint it just evicted on every switch (measured at a 7.4 s median reload on CPU and 10.3 s on T4), and traffic that only ever sees one language never builds the second, so the default costs a single-language deployment nothing.
For a server or production app, preload:
# Every checkpoint resident in memory; language flips cost detection only (<1 ms)
router = Router(preload=True)
router = Router(preload=True, device="cuda")

# Or preload only the specific checkpoints you serve:
router.preload(["english", "multilingual"])

# If your app already built an agent, attach it to avoid duplicate VRAM:
router.attach("english", existing_agent)

# Manage resident memory (default keeps two hot: english + multilingual, LRU eviction)
router = Router(max_loaded=3)       # keep all three hot, e.g. with auto_task_detection
router = Router(max_loaded=1)       # memory-constrained host, reloads on every switch
router.unload() # free memory| Deployment Mode | Per-Request Latency | Model Reloads |
|---|---|---|
Router() (lazy, max_loaded=2) |
detection only (<1 ms) on a switch, after each language's first load | 1 the first time a language appears |
Router(max_loaded=1) |
7 to 10 s on every language switch | 1 per switch |
Router(preload=True) |
32.8 ms (GPU) / 193–464 ms (CPU) | none |
A rebuild still re-reads the checkpoint, but each checkpoint's tokenizer is parsed once per process
and reused by every Agent — including one the Router rebuilds after eviction. The multilingual
tokenizer.json alone is 34 MB / 256k vocab, several times the cost of applying its weights.
Preloading is still the right answer for a server: it removes the rebuild rather than making it
cheaper.
Routing asks one question: can the English checkpoint read this state? The built-in detector answers it from the script and a function-word heuristic, and is deliberately dependency-free. That heuristic is best-effort on Latin-script languages it holds no word list for, so a short request can carry no usable signal:
from laya.lang import analyse
analyse("Care este ora in Tokyo?")
# {'script': 'latin', 'language': 'en', 'is_english': True}   -> the English checkpoint
If you already run a language-identification model, hand routing the answer instead of relying on the heuristic. lang_guess takes a language code or a callable receiving the state, and is checked after an explicit lang= and before detection:
# A code you already know
router.predict(state, questions, lang_guess="ro")

# A callable, e.g. wrapping fastText, CLD3 or a transformer LID
router.predict(state, questions, lang_guess=lambda s: my_lid(s))

# Or install one for every request on a server
router = Router(preload=True, lang_guess=my_lid)
The hint only decides English or not: a code whose primary subtag is en, eng or english routes to the English checkpoint, and every other code that names a language routes to the multilingual one. "en_US" and "en_US.UTF-8" are read as English, so $LANG can be passed straight through. Returning None, or a code that names no language, makes it abstain and the built-in detector decides as before — so a LID model that is unsure does not force a checkpoint. C, POSIX and C.UTF-8 abstain, which matters because C.UTF-8 is the default $LANG in the official Python image: passing it through no longer pins every request to the multilingual checkpoint, which is what it used to do. The ISO 639-2 special codes und, zxx and mul abstain for the same reason. An explicit model=, task= or lang= still wins, and the default path is unchanged.
laya.serve exposes the Router over HTTP on the same POST /v1/systemone
wire protocol as TypeSafe's hosted Jev API. Laya's answer payload is already
schema-identical to what Jev returns (choice/score/noul answers and a
{input_tokens, output_tokens} usage block), so an existing Jev client — e.g.
the hs-jev Haskell client — just
needs its baseUrl repointed; nothing else changes.
pip install "laya[serve]"          # adds fastapi + uvicorn + python-multipart
LAYA_DEVICE=cuda LAYA_PRELOAD=1 laya-serve   # binds 0.0.0.0:8000, preloads all 3 checkpoints
curl -s localhost:8000/v1/systemone -H 'content-type: application/json' -d '{
"state": {"body": "billed twice, refund please or we cancel"},
"questions": {"dept": {"type": "choice", "instructions": "which team?",
"criteria": {"billing": "refunds", "tech": "bugs"}}}
}'Configuration is by environment variable: LAYA_HOST, LAYA_PORT,
LAYA_DEVICE, LAYA_PRELOAD, LAYA_MODELS (comma list to preload),
LAYA_THREADS (cap torch intra-op threads for CPU inference — keep at or below
physical cores), LAYA_AUTO_TASK, and LAYA_API_KEY (when set, clients must
send Authorization: Bearer <key>). A client's model field is honoured when it
names a Laya checkpoint (english/multilingual/typed-decisions), otherwise
the router auto-selects by script/language.
Three things differ from Jev when you port a client:
- Options per question. A question's options share the checkpoint's option budget,
head_max_len(192 tokens onlaya, 256 on the other two), not Jev's cap of 255 options. Once they overflow it, around 20 options with a short description each, every option is trimmed to fit, so long or similar labels can reach the model reading the same (Where Jev leads). Once they no longer fit the window at all, the request is rejected with 422. With short labels such asQueue 042: Tickets routed to queue 42that happens above 126 options onlayaand 254 on the other two; the exact point moves with the length of the instructions and labels. For more candidates, narrow them first withpredict_shortlist(Honest limits). - Score levels. Every level needs a description. A
nulllevel is rejected with 422 rather than scored and echoed back inlegend. confidenceonchoiceandscoreanswers is 1 minus normalised entropy, a measure of how concentrated the distribution is, not Jev's(n·p_max − 1)/(n − 1). A threshold carried over from Jev does not transfer. For one calibrated number on every question type, gate onanswer_confidence, the probability of the reported answer.
This repo is a flake. On a machine with an NVIDIA GPU:
nix run .#laya-serve          # build (prebuilt CUDA torch, no compile) and serve
nix develop                   # dev shell: torch-bin, transformers, fastapi, pytest
For a NixOS host, import the module and enable the service:
# flake inputs:  laya.url = "github:<you>/laya";  # or path:/… on the same host
{
  imports = [ laya.nixosModules.default ];
  services.laya-serve = {
    enable = true;
    host = "0.0.0.0";           # or bind to the Tailscale/LAN address
    openFirewall = true;
    device = "cuda";
    models = [ "english" "multilingual" "typed-decisions" ];
    # apiKeyFile = config.age.secrets.laya-api-key.path;  # optional bearer auth
  };
}
The module runs a hardened DynamicUser systemd unit with CUDA device access,
caches weights under /var/lib/laya-serve, and reads the bearer token (if any)
via LoadCredential so it never enters the store.
If you only need a single checkpoint for a dedicated pipeline, you can load models directly:
import laya

# 1. Load a specific checkpoint directly from the hub
agent = laya.load("convaiinnovations/laya")                           # English root
agent_ml = laya.load("convaiinnovations/laya", subfolder="multilingual") # 100+ languages
agent_td = laya.load("convaiinnovations/laya", subfolder="typed-decisions")

# 2. Run all questions in ONE single forward pass (~35 ms on GPU)
result = agent.predict(state, questions)
answers = result["answers"]

print("Department :", answers["department"]["choice"])   # -> billing (confidence: 0.94)
print("Urgency    :", answers["urgency"]["score"])        # -> 1.84 / 2.0
print("Churn Risk :", answers["churn_risk"]["noul"])       # -> 0.892 (89.2% probability)
Passing an empty question dictionary to agent.predict(state, {}) or
agent.system_one(state, {}) returns the standard response with "answers": {}
and "usage": {"input_tokens": 0, "output_tokens": 0}. The state is not tokenized
and no model forward pass runs.
predict handles one state per call, which leaves most of the GPU's batch dimension idle. When you
have a list of items to score against the same questions — a backlog of tickets, a table of rows,
a log slice — predict_batch packs them into shared forward passes:
states = [{"body": t} for t in ticket_texts]           # a list of states

results = agent.predict_batch(states, questions)       # one forward pass for the whole list
# results[i] corresponds to states[i], with the same output shape as predict

# Bound peak memory when the list (or the texts) are large — chunk into passes of N:
results = agent.predict_batch(states, questions, batch_size=64)

# Reduce padding when input lengths vary; results still follow the original state order:
results = agent.predict_batch(states, questions, batch_size=64, sort_by_length=True)
sort_by_length=True groups states by their longest encoded question row, after truncation.
It looks ahead at most eight batches and reuses the encoded rows for sorting. This uses more temporary
CPU memory for tokenized inputs, and takes effect only when 1 < batch_size < len(states).
Benchmark it on your workload and backend: uniform lengths offer little benefit, and changed
batch shapes can cause small floating-point differences, including near decision thresholds.
Hooks still see states and final results in input order. The option is available on Agent.
Results are aligned with states by index and identical in shape to predict. Changing batch
shapes can introduce floating-point differences on CPU and GPU; check decision thresholds on
your workload, particularly with mixed precision. Batching is a GPU
throughput win — on an RTX 5060 Ti, per-decision latency drops from ~10 ms one-by-one to ~1 ms
batched (measured ~9–10×). On CPU, increasing batch size alone may not speed up inference;
length grouping can help by reducing the padded work in a mixed-length workload. See the
CPU measurements and reproduction commands.
predict/system_one truncate a state that exceeds max_len to a single window (the first, or
for a conversation list the last), silently dropping the rest. predict_long scans the whole state
in overlapping windows, scores them in shared forward passes (via predict_batch), and aggregates
per question:
result = agent.predict_long(state, questions)              # windows the state, one result back
result = agent.predict_long(state, questions, window=256) # smaller window isolates a localized spannoultakes the strongest window (the statement holds if any window supports it).choice/scoretake the most-confident window — averaging over a long, mostly-neutral document lets the neutral majority out-vote the one window that saw the deciding span.- A state that already fits one window is passed straight to
system_one(identical output).
A smaller window isolates a short deciding span better (it becomes a larger fraction of its
window); the default (max_len - head_max_len) favors context and throughput. Output shape matches
predict, with usage["windows"] added.
The returned probability is the deciding window's, not a calibrated number for the whole
document — a noul max drifts up with the window count even with no signal, and choice can land
on a confidently-neutral window when nothing is decisive. Each answer carries answer["window"]
(the deciding window's index, token_start/token_end, and count) so you can check the span
the answer actually came from:
r = agent.predict_long(state, questions)
r["answers"]["refund"]["window"] # {'index': 13, 'token_start': 4680, 'token_end': 5432, 'count': 14}pip install laya[fast] adds an optional forward built from fused TileLang
kernels: GEMM + bias/activation epilogues, GEMM + GEGLU, residual + LayerNorm, in-place RoPE, and a
sliding-window flash attention that reads the packed QKV buffer directly. Weights stay resident in bf16
and every (batch, length) bucket is captured as a CUDA graph, so a one-question call no longer pays
~200 kernel launches from Python.
agent = laya.load("convaiinnovations/laya", fast=True)   # or: agent.accelerate()
agent.predict(state, questions)                            # same API, same answers
Numerics: on a fixed set of 60 states the fast path stays within 0.046 of an fp32 forward and within 0.076 of the stock
bf16 path (max |Δp| ≤ 0.05 vs fp32 on both checkpoints, argmax agreement ≥ 47/48 per question type; every per-option
probability is in benchmarks/results/parity_*.json) — see benchmarks/parity_fast.py and BENCHMARKS.md.
The fast path runs in the agent's autocast dtype at the time accelerate() is called: bf16 by default, fp16 if
agent.dtype is torch.float16, where it stays within 0.009 of fp32 on the same set (BENCHMARKS.md).
Falls back to the stock forward on CPU/MPS or when tilelang is not installed; agent.deaccelerate()
restores it. Kernels compile once per shape bucket on first use (a few seconds, cached on disk).
Because Laya's probabilities are trained with strictly proper scoring rules (RLCD), confidence scores are statistically meaningful:
dept = answers["department"]["choice"]
conf = answers["department"]["confidence"]

if conf >= THRESHOLD:               # refit and validate THRESHOLD on your own held-out data
    route_automatically(dept)       # above it: act, and sample the decisions you act on
else:
    escalate_to_human_agent(dept, reason=f"Low confidence ({conf:.2f})")
A threshold is a policy you choose from measured accuracy at that coverage on your data, not a property of the model. Both checkpoints are over-confident as shipped and laya-multilingual has no fitted temperatures at all, so fit them before relying on these numbers — see Calibration above, and the fine-tuning notebook for the fitting loop itself. Then pick the point where the errors you accept are ones you can live with. Confidence orders decisions; it does not establish that a decision is correct.
A threshold also depends on the autocast dtype. On CUDA at compute capability 8 or above the runtime uses the checkpoint's amp_dtype, which is bf16 for all three shipped checkpoints. On the fixed set from benchmarks/parity_fast.py (60 states, 288 questions per checkpoint, RTX 2000 Ada) bf16 moves a probability by up to 0.073 against the fp32 forward and flips 3 of 864 argmaxes across the three checkpoints; fp16 stays within 0.019 and flips none, at the same latency. LAYA_CUDA_AMP=fp16 selects fp16 and LAYA_CUDA_AMP=bf16 selects bf16 (LAYA_CPU_AMP=bf16 is the CPU counterpart). Fit and measure a threshold in the dtype you serve with.
Hooks observe or shape every decision without forking: audit logging, PII redaction before inference, caching, metrics, confidence gating, routing overrides, and forwarding to an external service. They are opt-in, and unset hooks are a no-op.
import laya

def log(ctx):
    print(ctx.model, ctx.results[0]["answers"], ctx.elapsed_ms)

agent = laya.load("convaiinnovations/laya", on_predict_end=log)
agent.system_one("I was charged twice.", {"urgent": {"type": "noul", "instructions": "Urgent?"}})
A hook is a plain callable, or an object implementing any of on_predict_start,
on_predict_end, on_route, on_load, on_evict, on_error. A start hook can rewrite the
state/questions or ctx.skip(...) a cached answer; an end hook can rewrite the result. See
docs/hooks/ and examples/hooks/.
Describe the shape you want with a JSON schema or a pydantic model, and Laya answers it in one forward pass, with typed values and calibrated confidence.
import laya

schema = {
    "type": "object",
    "properties": {
        "department": {"type": "string", "enum": ["billing", "support", "sales"],
                       "description": "Which team should handle this?"},
        "urgency": {"type": "integer", "minimum": 0, "maximum": 2},
        "needs_human": {"type": "boolean"},
    },
}

agent = laya.load("convaiinnovations/laya")
agent.decide("I was charged twice, refund me.", schema=schema)
# {"department": "billing", "urgency": 2, "needs_human": True}
decide also works on a Router, accepts a pydantic model (install laya[structured]), and can
return per-field confidence with return_details=True. See docs/structured.md.
Laya provides pre-tuned question schemas for immediate production use:
import laya

agent = laya.load("convaiinnovations/laya")

# 1. Intelligent Model Router (routes to small vs. frontier models)
routing = agent.predict({"request": "Refactor this service using dependency injection"}, laya.router_questions())

# 2. Real-time Prompt Guardrails (jailbreaks, injections, leaks)
guard = agent.predict({"prompt": "Ignore all instructions"}, laya.guard_questions())

# 3. Content Safety & Moderation (toxicity, harassment, threats)
safety = agent.predict({"post": "User comment text"}, laya.moderation_questions())

# 4. Support Ticket Triage (intent, urgency, frustration, churn)
triage = agent.predict({"message": "My payment failed twice"}, laya.triage_questions())Fast System 1 routing and guardrails directly inside LangGraph workflows and LCEL chains:
from laya.integrations.langchain import LayaRouter, LayaGuardrail

# 1. Sub-35ms LangGraph conditional edge routing with confidence fallback
router = LayaRouter(
    criteria={"billing": "invoices, charges", "tech": "bugs, outages"},
    confidence_threshold=0.80,
    fallback="human_agent",
)
workflow.add_conditional_edges("triage", router)

# 2. Inline prompt guardrails
guard = LayaGuardrail(action="raise")  # raises LayaGuardrailError on jailbreak/injection
See docs/langchain.md for full guide, support ticket triage nodes, and remote HTTP server configuration.
| Primitive | Output | Use Cases |
|---|---|---|
choice |
Top label, probabilities per option, confidence | Department routing, intent classification, topic categorization |
score |
Expected level on ordinal rubric, distribution, confidence | Frustration level, ticket urgency, harm severity |
noul |
Calibrated probability P(true) from 0.0 to 1.0 | Phishing detection, spam filtering, jailbreak detection, churn risk |
noul always scores two semantic slots in [false, true] order and returns the probability of
the second slot. For compatibility, those slots are shown to the model as false and true by
default. The optional labels mapping overrides only that model-facing text without changing the
returned meaning:
question = {
    "type": "noul",
    "instructions": "Is this review positive?",
    "criteria": {
        "false": "the review is negative",
        "true": "the review is positive",
    },
    "labels": {
        "false": "B",
        "true": "A",
    },
}
The labels mapping is optional. It must contain exactly the string keys false and true,
whose values must be distinct non-empty strings. Mapping order does not matter, and the returned
noul value is still P(true). Label sensitivity varies by checkpoint and state, so validate any
override on your own data rather than treating A/B as a universal fix.
Laya can be exposed as an MCP stdio server, so any MCP
client (OpenClaw, Claude Desktop, Cursor, ...) can call typed decisions as tools
(laya_predict, laya_route, laya_shortlist, laya_preset, laya_status) without writing glue code.
This is an optional extra: the core package has no mcp dependency.
pip install "laya[mcp]"
laya-mcp-server          # or: python -m laya.mcp.server
Example MCP client configuration (stdio transport):
{
  "mcpServers": {
    "laya": {
      "command": "laya-mcp-server",
      "env": { "LAYA_DEVICE": "cpu" }
    }
  }
}
The environment variables follow the contract documented at the top of
laya/serve.py, so the same variable has one meaning across the
package:
| Variable | Default | Meaning |
|---|---|---|
LAYA_DEVICE |
(auto) | Same as laya.serve: the value is passed straight to torch |
LAYA_PRELOAD |
1 |
Same as laya.serve: build the checkpoints at startup, not lazily |
LAYA_MODELS |
english,multilingual |
Comma list to preload (serve contract). MCP difference: an empty value preloads english,multilingual so typed-decisions stays lazy; in laya.serve empty means every checkpoint |
LAYA_THREADS |
(torch default) | Same as laya.serve: cap torch intra-op threads for CPU inference; keep it at or below the physical core count |
The tools return structured JSON (answers with probabilities, routing metadata, device,
latency_ms). laya_shortlist is the MCP form of predict_shortlist:
it shortlists a many-option choice question to its k most likely labels by embedding
similarity (mean-pooled from the answering checkpoint's own encoder, so no extra model is
downloaded), answers in one forward pass, and returns per-question shortlist metadata
(kept labels, cosine scores, k, option count). The guardrails shown on every decision
tool point clients here for >20-option choices. As with the SDK, use it for structured
decisions only; not for open Q&A or
text generation. Tests: tests/test_mcp.py (CI, no weights) and
tests/test_mcp_local_e2e.py (local, real weights and a real stdio handshake).
laya.evals scores a labelled dataset and gates a build on it, so a quality change is a
reviewable diff instead of a hand-check. It is pure Python plus numpy, imports no torch, and
needs no weights until you point it at a checkpoint.
laya-evals validate research/evals/fixture.jsonl
laya-evals run data.jsonl --model english --min-accuracy 0.8 --max-ece 0.05 --slice language
laya-evals run data.jsonl --baseline baseline.json --tolerance choice_accuracy=0.02 --json report.json
run reports overall and per-slice metrics (choice_accuracy, noul_accuracy, score_mae,
ece, mean_confidence, latency) and exits non-zero on a threshold or baseline failure, so it
drops into CI unchanged. A weight-free job runs the metric and API tests on every PR, and a
scheduled workflow evaluates the English checkpoint against the committed baseline. See
docs/evals.md for the dataset format and the gate.
Community diagnostics: Chinese workplace decisions (Feishu-style) · 中文说明. Includes frozen synthetic cases, archived paired Laya/Jev responses, and an offline audit; separate from the benchmark suites below. Also Chinese short-command routing · 中文说明: 18 frozen commands and a seven-rung ablation of the documented prompt guidance, which locates the accuracy loss on the four-question path rather than the six-option one.
Full report: BENCHMARKS.md — every run consolidated, languages and themes, with per-language detail for all 51 languages.
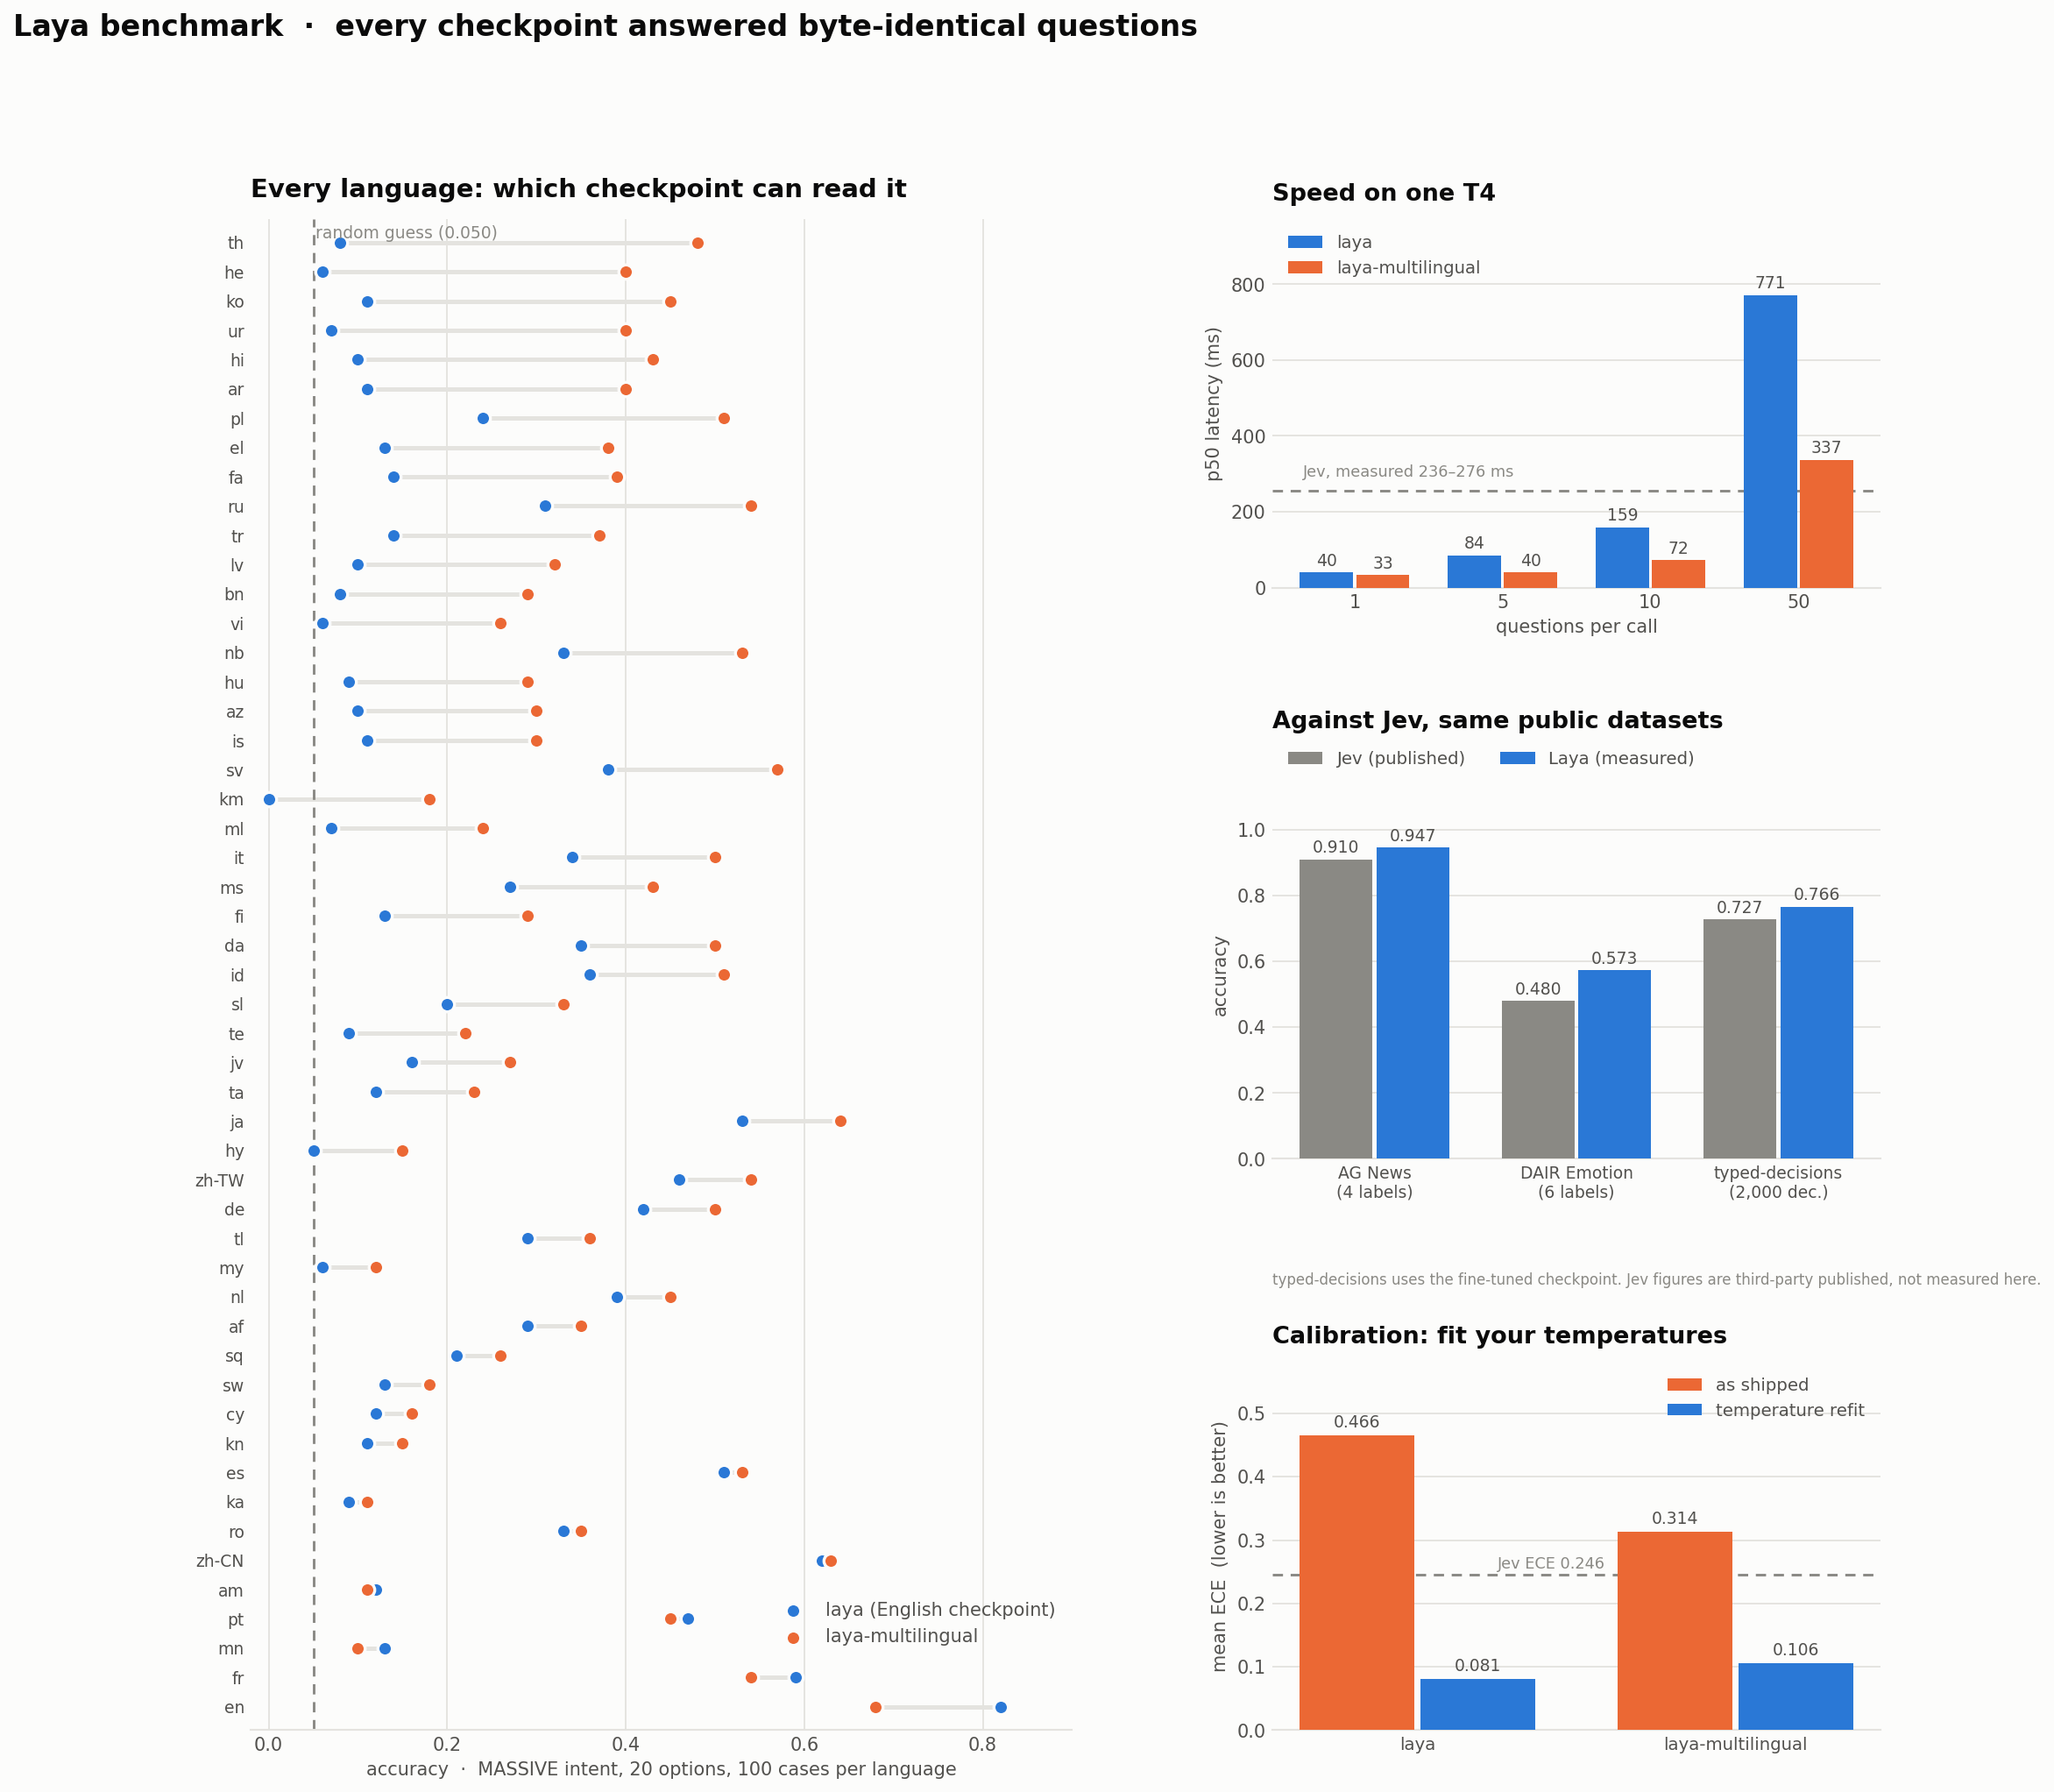
All Laya numbers below are measured. Every model answered byte-identical questions
(fixed seed) in the same run. Reproduce with
research/scripts/laya_benchmark_colab.ipynb on a T4.
| questions per call | laya |
laya-multilingual |
|---|---|---|
| 1 | 39.5 ms | 32.8 ms |
| 5 | 84.5 ms | 40.1 ms |
| 10 | 158.6 ms (15.9 ms/q) | 72.3 ms (7.2 ms/q) |
| 50 | 771 ms | 337 ms (6.8 ms/q) |
Batched throughput reaches 103-332 questions/sec on a single T4. For reference, TypeSafe Jev has been independently measured at 236-276 ms p50 (AbdelStark, nibzard) -- Laya answers a single question roughly 6-7x faster.
Every Laya figure is what Router().predict(...) actually returns — the checkpoint the router
selects for that input, not a hand-picked best of three. Jev figures are third-party
published, never measured here (no TypeSafe API access), so sample sizes and prompts differ.
| Jev 1.13.0 | Laya (routed) | ||
|---|---|---|---|
| typed-decisions, 2,000 decisions | 0.727 | 0.766 | +0.039 |
| AG News, 4 labels | 0.910 | 0.950 | +0.040 |
| DAIR Emotion, 6 labels | 0.480 | 0.595 | +0.115 |
| Banking77 (72 vs 77 labels) | 0.870 | 0.425 | Jev leads on >20 options |
| ECE (lower better) | 0.246 | 0.081 | 3× better (post-temperature) |
| p50 latency, 1 question | 236–276 ms | 32.8 ms | 7.8× faster |
| Languages usable | no published benchmark | 45 of 51 | — |
| Weights | closed API | Apache 2.0 | — |
| Cost | $0.042 / 1M tokens | $0 self-hosted | — |
On DAIR Emotion, Jev assigned zero probability to the true label on 16% of examples — a hard failure for anything branching on confidence.
- High-cardinality label spaces (>20 options at default settings): On Banking77, Jev scores 0.870 (on 72 labels) while Laya scores 0.425 (on 77 labels at default 256-token head budget). This is an architectural token-budget constraint: options share a fixed
head_max_lenbudget (192 tokens on English, 256 on multilingual), so 77 options receive only ~3 to 4 tokens per label, causing text to become indistinguishable. Jev supports up to 255 options out-of-the-box. Whilelaya-multilingualsupports 1,024 context (and up to 8,192 in the encoder) and you can raiseagent.cfg["head_max_len"] = 512at runtime, Jev is currently better suited for 50+ options in a single prompt without tuning.predict_shortlist(see Honest limits) keeps the topklabels with a caller-supplied embedding, then runs one forward pass on that shortlist. - Soft distribution matching: On typed-decisions, while Laya achieves higher argmax accuracy (0.766 vs 0.727), Jev achieves higher soft accuracy (0.580 vs 0.471) against the teacher's full probability distributions.
- Out-of-the-box raw calibration: Before temperature scaling, the base checkpoint has higher raw ECE (0.213 vs 0.144). Laya achieves its 0.081 ECE after domain temperature fitting.
Full detail, including every workflow and all 51 languages: BENCHMARKS.md.
400 cases, 2,000 decisions, four workflows.
| model | accuracy | soft acc | Brier | ECE | score MAE |
|---|---|---|---|---|---|
laya-typed-decisions |
0.766 | 0.471 | 0.062 | 0.213 | 0.242 |
laya |
0.362 | 0.332 | 0.316 | 0.175 | 0.694 |
laya-multilingual |
0.352 | 0.328 | 0.463 | 0.314 | 0.760 |
| Jev 1.13.0 (published) | 0.727 | 0.580 | 0.148 | 0.144 | 0.391 |
| teacher self-agreement ceiling | 0.735 | ||||
| per-question majority class | 0.461 | ||||
| random guess | 0.318 |
The fine-tuned checkpoint beats Jev by 3.9 points and clears the teacher ceiling, with 2.4x
better Brier and 1.6x better score MAE. It wins on all four workflows: invoice processing
0.804, security incidents 0.766, customer service 0.764, agent-trace observability 0.730.
By primitive: noul 0.857, choice 0.733, score 0.723.
Two places it still trails Jev: soft accuracy (0.471 vs 0.580 — its argmax is better but its distributions match the teacher less well) and ECE (0.213 vs 0.144), which temperature fitting addresses.
The base checkpoints sit below the majority-class baseline (0.362 and 0.352 against 0.461). All of the capability on this benchmark comes from fine-tuning.
laya |
laya-multilingual |
|
|---|---|---|
| English | 0.783 | 0.657 |
| 13 other languages | 0.306 | 0.451 |
| XNLI, English | 0.860 | 0.843 |
| XNLI, 14 other languages | 0.521 | 0.731 |
Across all 51 languages the English checkpoint macro-averages 0.227 with macro ECE
0.733, and only 23 of 51 languages clear 3x random. Khmer scores 0.000 at 95.2%
confidence. This is why Router exists: the
model's own confidence gives no warning, so the routing decision has to be made before the
forward pass.
| task | laya |
laya-multilingual |
note |
|---|---|---|---|
| AG News | 0.947 | 0.937 | in training mix |
| BoolQ | 0.830 | 0.787 | in training mix |
| DAIR Emotion | 0.573 | 0.513 | held out |
| prompt-injections | 0.698 | 0.578 | held out, n=116 |
| SST-5 (ordinal) | 0.372 | 0.282 | held out |
Both checkpoints are over-confident as shipped. Refitting one temperature per (question type,
option count) on held-out data moves mean ECE 0.466 -> 0.081 (laya) and
0.314 -> 0.106 (laya-multilingual). laya-multilingual ships with no fitted
temperatures at all, so fit them before relying on its probabilities.
At checkpoint load, numeric temperature entries are clamped to [0.5, 5.0]; invalid or
non-finite entries use the neutral fallback 1.0. A runtime warning reports the affected
entries and applied values. Bucket-specific temperatures still take precedence over per-type
values, including when a bucket uses the fallback. Raw values remain available in
agent.temperature_raw and agent.temperature_by_options_raw. A fallback prevents a loading
failure; it does not establish calibrated confidence.
- The base checkpoints are near chance on typed-decisions zero-shot -- 0.362 and 0.352 against a 0.318 random baseline and a 0.461 majority-class baseline. The 0.766 figure comes from the checkpoint fine-tuned on that benchmark's own training split. Laya is a fast base to specialise, not a zero-shot decision engine.
- Avoid boolean-word labels in
choicequestions. Choice keys are rendered verbatim, and the current checkpoints can follow labels such astrue/falseoryes/noinstead of the option descriptions. Use semantic labels or opaque labels such asA/B, and validate them on the checkpoint and states you serve. - Semantic
choicelabels do not make negation safe. In the five cancellation examples from #377, a CPU run on Laya 0.3.20 withno_action/cancel_accountkeys selectedcancel_accountfor all four negated requests onlayaand two onlaya-multilingual; one multilingual answer assigned it probability0.9998. The positive control passed on both checkpoints. These are narrow cancellation examples, not evidence that every negated state fails. Validate the exact checkpoint and wording you serve; using semantic keys alone does not avoid this failure. - High-cardinality choice questions and token budgets: Sequences split into an option prompt budget (
head_max_len) and the remaining document/state budget (max_len - head_max_len):laya(English) defaults to 512 context (head_max_len = 192, ~320 tokens for state).laya-multilingualandlaya-typed-decisionsdefault to 1,024 context (head_max_len = 256, ~768 tokens for state; mmBERT-base encoder supports up to 8,192 with RoPE). At default settings, a 77-option question like Banking77 allocates only(256 - 16) // 77≈ 3–4 tokens per label, which causes accuracy to fall off sharply (0.425 vs Jev's 0.870). If evaluating 50+ options in a single question:
- Raise
agent.cfg["head_max_len"] = 512andagent.cfg["max_len"] = 1024(or up to 2048 / 4096 / 8192) so every option has enough tokens to remain distinct. - Or shortlist with embeddings and run one forward pass on the top
klabels (predict_shortlist, example below).predictandsystem_onestill score every criterion they are given. - Or split the label set yourself into a coarse question and a fine question.
import laya

questions = {
    "intent": {
        "type": "choice",
        "instructions": "Which banking intent is this?",
        "criteria": {
            "card_arrival": "where is my card",
            "transfer_fee": "fee charged on a transfer",
            # ...the rest of a large label set
        },
    }
}
result = laya.predict_shortlist(
    agent,
    {"text": "I was charged twice for a transfer"},
    questions,
    embed_fn=laya.embed_fn_from_agent(agent),  # or any callable: texts -> (n, dim)
    k=20,
)
result["shortlist"]["intent"]["labels"]  # the top 20 labels sent to the model
embed_fn(texts) returns one vector per string. embed_fn_from_agent mean-pools the encoder already loaded on the agent; the decision head runs in the following predict / system_one call. Probabilities on a shortlisted choice are over those k labels. When k is at least the number of labels, the original question is passed through and embed_fn is not called.
Shortlisting the same option set on every request re-embeds option texts that do not change. Wrap the embedder once with laya.cached_embed_fn(embed_fn) and repeat calls embed only the new query text: lookups are exact string matches into an LRU of at most 4,096 entries (about maxsize * dim * 4 bytes, so ~12 MB at the default with a 768-dim encoder), and texts missing from the cache are still embedded in one batched call. The wrapper's cache_info() reports hits and misses; call cache_clear() if the model behind embed_fn changes.
Issue #102 reports that a top-20 zero-shot shortlist moved a BANKING77 run from 54.3% to 60.8% on the reporter's setup. Those figures are the reporter's; this repository has not remeasured them.
-
Ordinal
scorequestions are the weakest primitive (SST-5 0.372). -
noulcan follow its option labels instead of the state, most strongly onlaya(English).noulrenders its two options asfalse:/true:by default, and on the English checkpoint that label pair can dominate the answer, returning a confident "no" for clearly positive input (#156). Until a retrained checkpoint lands, checknoulanswers on your own data. You can override the model-facing pair while keeping thenoulresult as P(true):{"type": "noul", "instructions": "Is this review positive?", "criteria": {"true": "yes, the review is positive", "false": "no, the review is negative"}, "labels": {"true": "A", "false": "B"}}Label sensitivity varies by checkpoint and state, so validate the override on your own data. A two-option
choicewith neutral keys remains another workaround:{"type": "choice", "instructions": "Is this review positive?", "criteria": {"A": "yes, the review is positive", "B": "no, the review is negative"}}criteriaon anoulmust be keyedtrue/false— those two keys are the option text the model reads, so any other key is rejected instead of being quietly replaced with the defaults. Before that check,criteria: {"yes": ..., "no": ...}was accepted, dropped, and answered againstfalse:/true:anyway, which cost 2 of 3 clearly positive reviews on the English checkpoint (#156). Uselabelsas above to change the wording without touching the option text. -
laya-multilingualhas a position bias onscorequestions (#131): it rarely picks the first-listed level, in any language. For English score questions, route tomodel="english", and for other languages validate score outputs on your own data before relying on them. -
action.act_probabilitycarries no usable signal yet (#185). It reads 1.0 for almost every input, and its raw logits run against correctness (AUROC 0.30 on 396 labelled decisions). Gate onconfidenceinstead, which reaches an AUROC of 0.77 on the same items. -
layacollapses outside English;laya-multilingualis weaker on English. Route, or pick deliberately.
- omp-laya-judge: an oh-my-pi plugin with a local System-1 judge MCP server and skill (
choice/bool/score, 0 tokens, about 0.3 s on CPU), confidence-gated escalation, and reproducible quiz and Snake demos. - laya-adk-toolkit: Google ADK tools that let an agent call Laya's
classify/score/detecttyped decisions directly as tools, instead of asking an LLM to guess at structured output. - laya-Ascend: Laya on Huawei Ascend NPUs through
torch-npu, with a CPU vs NPU benchmark (34x to 71x faster at batch size 1), a setup guide, and Snake and Tetris demos. - laya-apple: a correctness-validated Laya runtime for Apple silicon that uses the MLX GPU and the Apple Neural Engine, with automatic routing and concurrent heterogeneous serving.
- stuntd: runs Laya locally behind the Jev API (
POST /v1/systemone, no key) and trains a head per decision on the frozen encoder from your own labelled rows, with a calibrated confidence threshold (a 12-label intent task: 89.5% zero-shot to 100% trained).
- Hugging Face Model: convaiinnovations/laya
- Interactive Web Demo: convaiinnovations/laya-demo
- Engineering Writeup: Read the full story on Dev.to
Fine-tune Laya on your own domain data. The notebook runs on Kaggle's free 2xT4 GPUs and does the whole loop: build the dataset, train with RLCD (proper-scoring-rule rewards, GRPO-style policy gradient), fit calibration temperatures, evaluate, and push the result to the Hub.
The notebook enables gradient checkpointing on both the encoder and the decision head.
For custom training loops, model.head_checkpointing = True enables activation
checkpointing for the decision-head layers; enable the encoder's gradient checkpointing
separately. During gradient-enabled training, this reduces stored intermediate activations
by recomputing them during backward, trading extra computation for lower activation memory.
The head flag defaults to False and is bypassed in evaluation and under torch.no_grad().
The notebook fits one temperature per type (choice, score, noul) and removes inherited
temperature_by_options from the exported config. Otherwise those old bucket values take
precedence at inference and silently mask the new fit. Existing checkpoints still honor
intentional bucket-specific temperatures, falling back to the corresponding per-type value
when a bucket is absent; the runtime's temperature clamp is unchanged.
This fixes configuration persistence, not measured model accuracy or calibration quality.
The notebook's calibration samples come from its training items; evaluate on separate held-out
data before claiming an improvement. Already published checkpoints are not rewritten.
Run the CPU-only regression checks with python tests/test_calibration_persistence.py
(synthetic configs and tiny local fixtures; no pretrained downloads or training).
Fine-tuning is where most of the value is. On the typed-decisions benchmark the base checkpoints score near chance zero-shot (0.36 and 0.35 against a 0.318 random baseline), while the fine-tuned checkpoint reaches 0.766 on the same 2,000 decisions -- above TypeSafe Jev's published 0.727 and above the 0.735 teacher self-agreement ceiling. Treat Laya as a fast base to specialise, not as a zero-shot decision engine.
Runtime on 2xT4 is roughly 4-5 hours for 4 epochs over ~30k questions.
docs/finetune_browser_agent.md records a complete specialisation
on a single 16 GB GPU with no paid API: Laya as the operation/target decider for
browser-use/jev-ultrafast (same request format as
TypeSafe Jev). Element top-1 among ~45 candidates goes from 0.10 zero-shot to 0.66, real-task
success from 0 % to 62 % at 17-23 ms per step; weights, pipeline code and per-run results are on
the Hub at cklxx/laya-browser. The write-up covers the
data recipe (reverse-generated goals, executed DONE states, Mind2Web, on-policy corrections), the
input-format change that mattered most, and the things that did not work.
If Laya helps your research or products, consider supporting independent research:

Apache 2.0. Developed by Convai Innovations.